Quick Tips · Tip 03 · 0:21
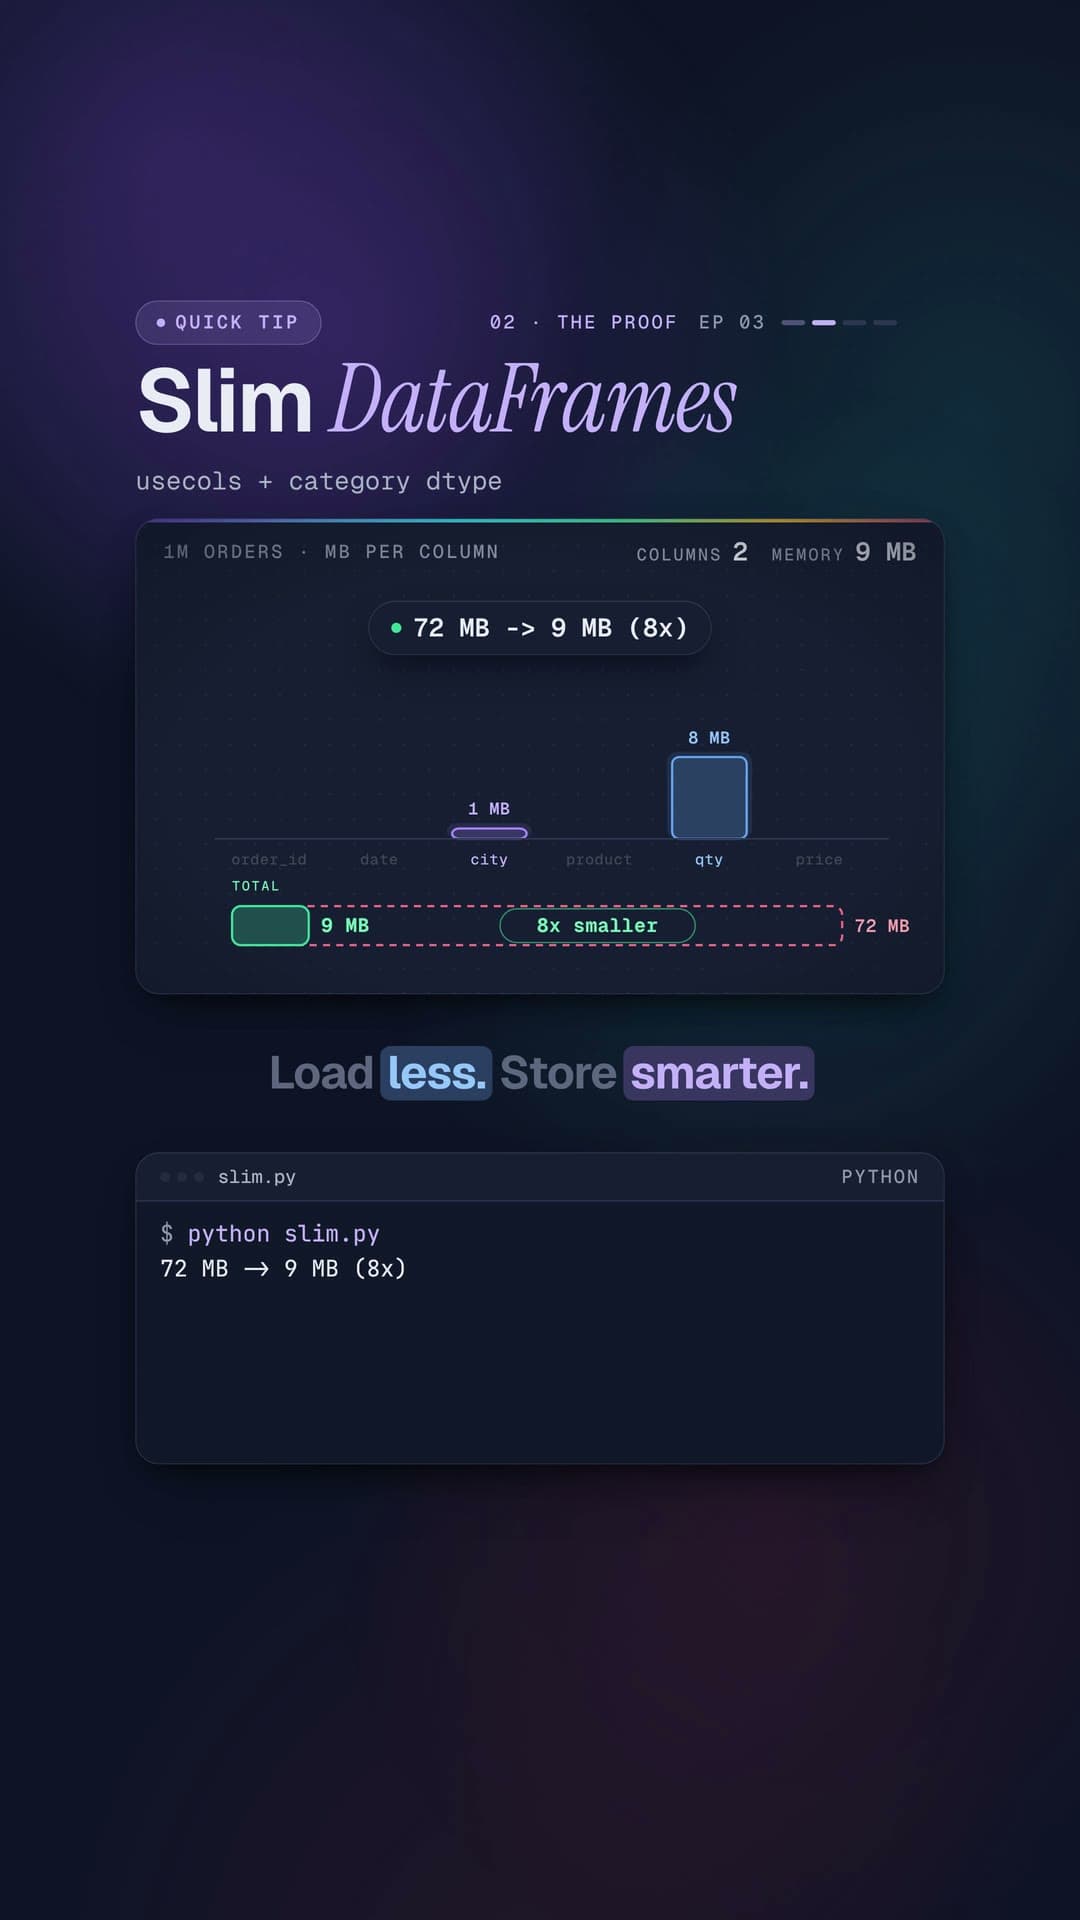
How to reduce pandas memory usage 8x with two read_csv arguments
Load only the columns you need with usecols and store repeated text as category. The same data drops from 72 MB to 9 MB, measured with memory_usage(deep=True).
Key moments
What you’ll needPython 3.10+, pandas
What you’ll need
- python.org/downloads →
 Python 3.10 or newerRuns the code. Check yours with
python3 --version. - code.visualstudio.com →
 VS Code or CursorEither works; so does any editor you like.
- git-scm.com/downloads →
 gitOptional for a tip: to keep your own copy of the code.
 pandas 2.2+Tables
pip install "pandas>=2.2"
Set it up
- 1Make a virtual environmentIt keeps this project's packages separate from the rest of your computer.
python3 -m venv .venv
source .venv/bin/activate
- 2Install the package
pip install "pandas>=2.2"
- 3Run itSave the snippet below as slim.py. It reads sales from the video's demo data, which isn't published, so point it at your own file.
python3 slim.py
slim.pyOpen on GitHub →
import pandas as pd
from sales import CSV  # 1M orders, 6 columns
mb = lambda d: d.memory_usage(deep=True).sum()/1e6
a = mb(pd.read_csv(CSV))
b = mb(pd.read_csv(CSV, usecols=["city", "qty"],
                   dtype={"city": "category"}))
print(f"{a:.0f} MB -> {b:.0f} MB ({a/b:.0f}x)")
Transcript
Your pandas DataFrame is eating memory it doesn't need. Measure the full load, deep equals True. Now read only the columns you need, and store repeated text as category. 72 MB down to 9.
Eight times smaller. Load less. Store smarter.
Read the lesson on GitHub →- #pandas
- #python
- #datascience
- #dataengineering