Datanatomy
VideosBlogCodeAboutLinks
/

    GitHub
    DatanatomyCode is MIT on GitHub
    YouTubeTikTokInstagramThreadsGitHubRSS
    Datanatomy
    VideosBlogCodeAboutLinks
    /

      GitHub
      12 videos

      Data engineering, taken apart.

      Long explainers, 30-second cuts and quick tips. Open one for the player, the key moments, the full transcript and the code.

      All 35Machine learning 14AI engineering 4Data engineering 11Methodologies 4Software engineering 2

      1–11 of 11 vertical videos

      Series
      Length
      Watch on
      Sort

      Full builds on YouTube

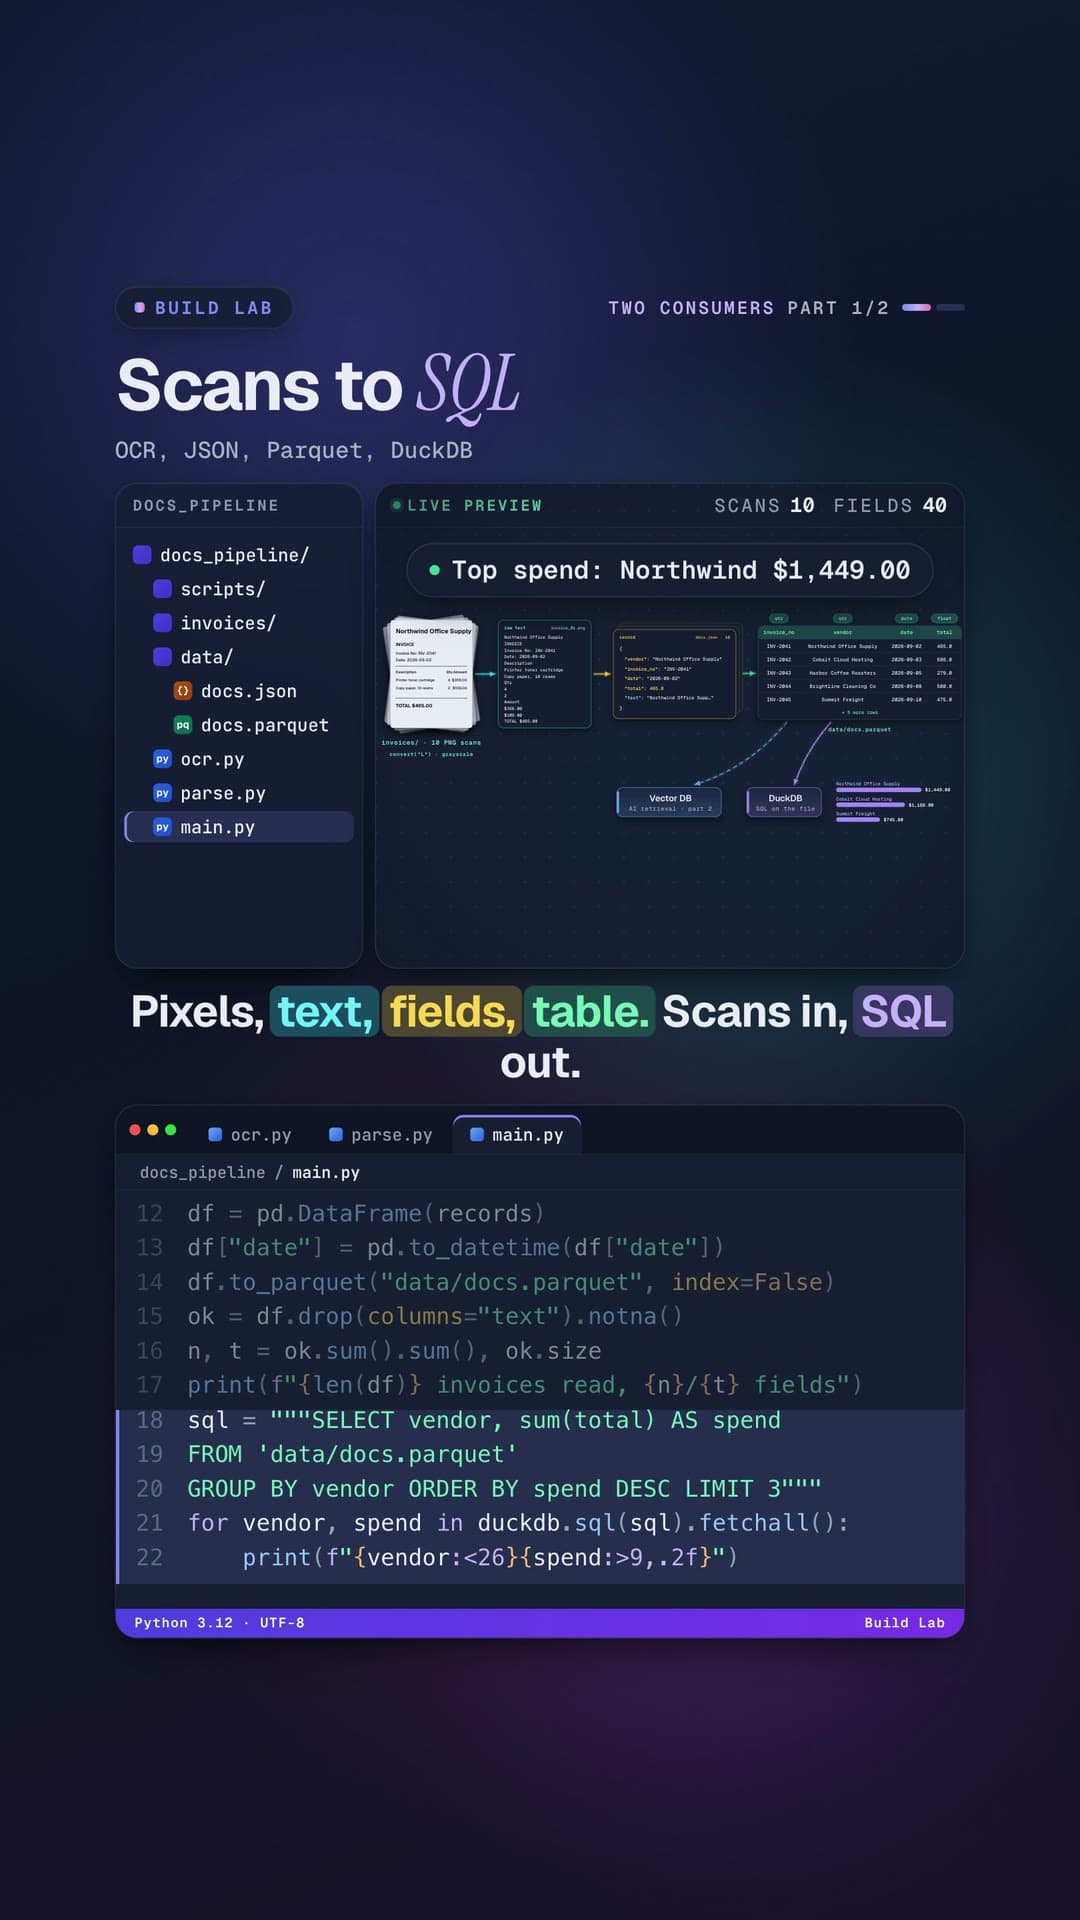
      Thumbnail: a real invoice scan turning into a Parquet table6:53Full build on YouTube · Data engineeringTurn Scanned Documents into Data with Python (OCR, DuckDB, RAG)Ten scanned invoices go in. A table you can query with SQL, and an index you can ask in plain English, come out.
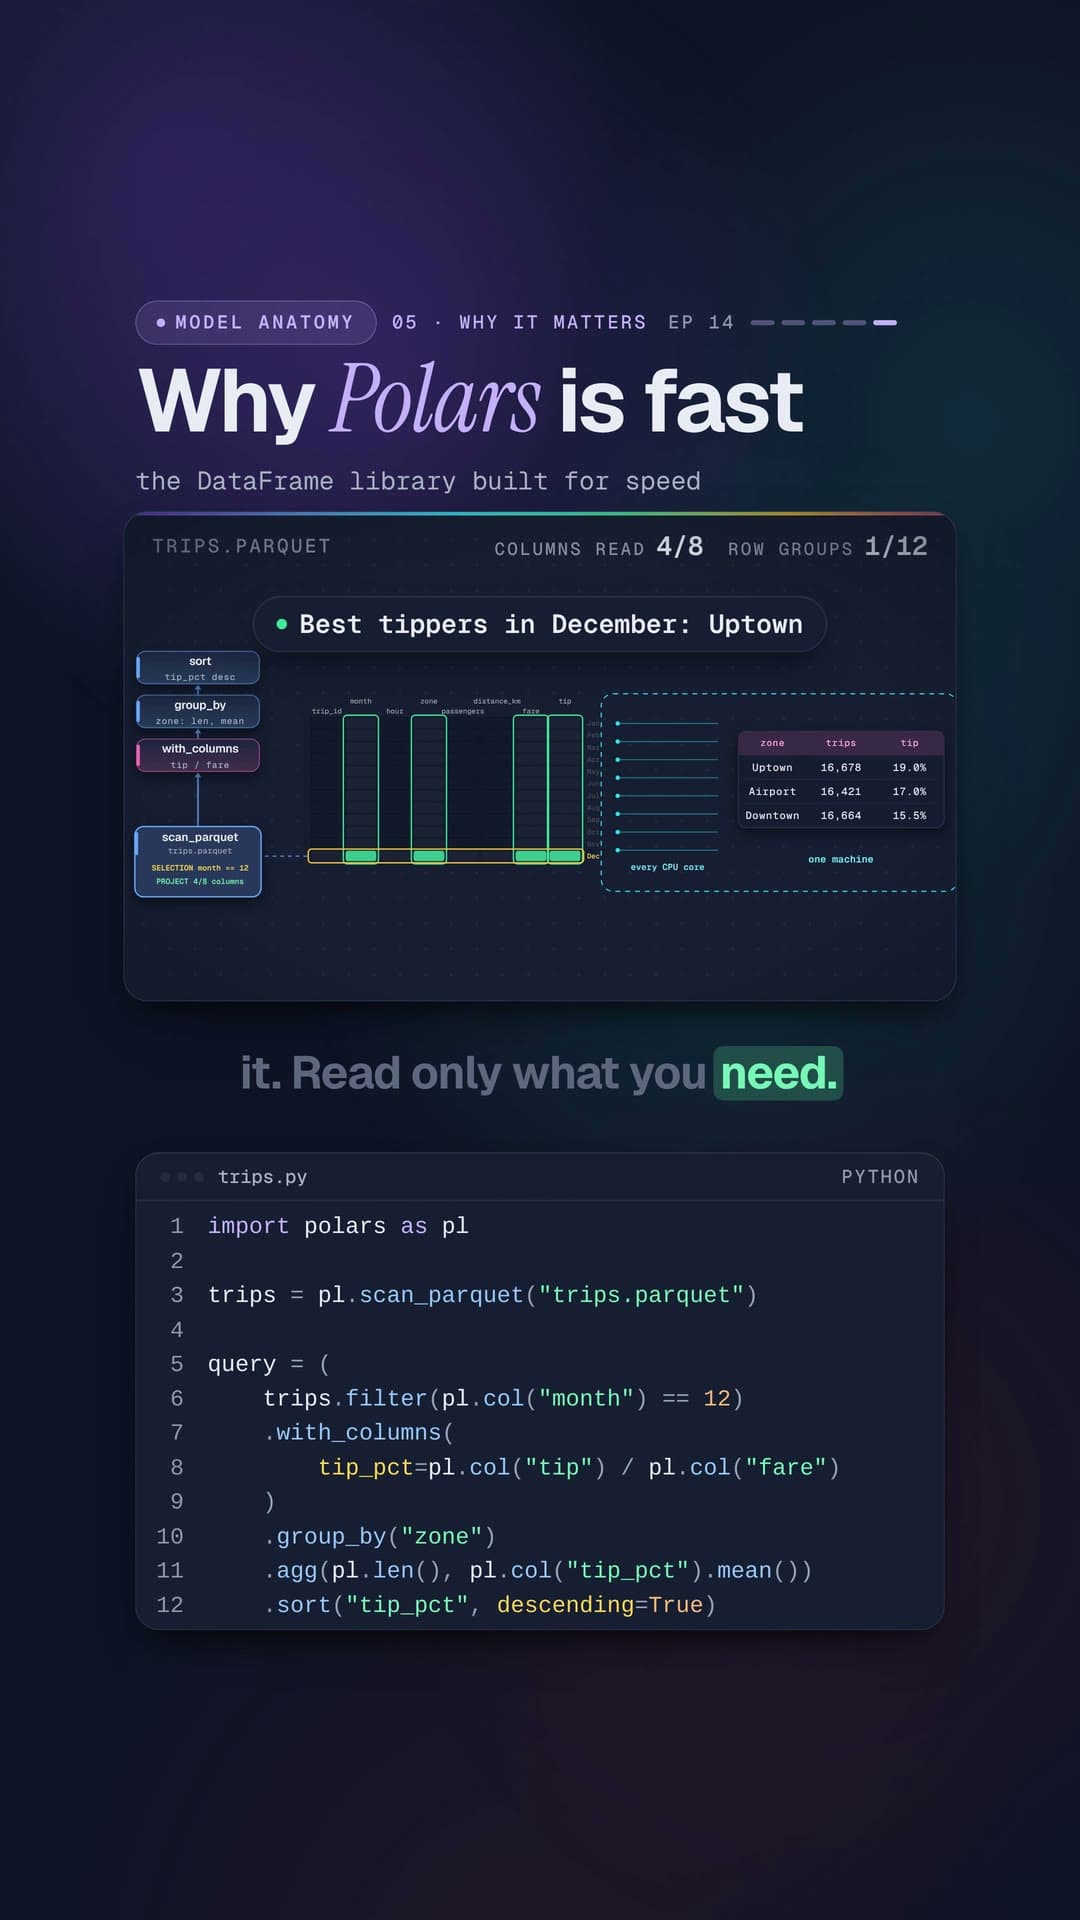
      • Frame from Why Polars is fast: Why Polars is fast, the DataFrame library built for speed2:01Data engineeringWhy Polars is fast
      • Frame from PySpark: 100 million rows: How Spark scales, partitions, lazy plans, shuffles1:51Data engineeringPySpark: 100 million rows
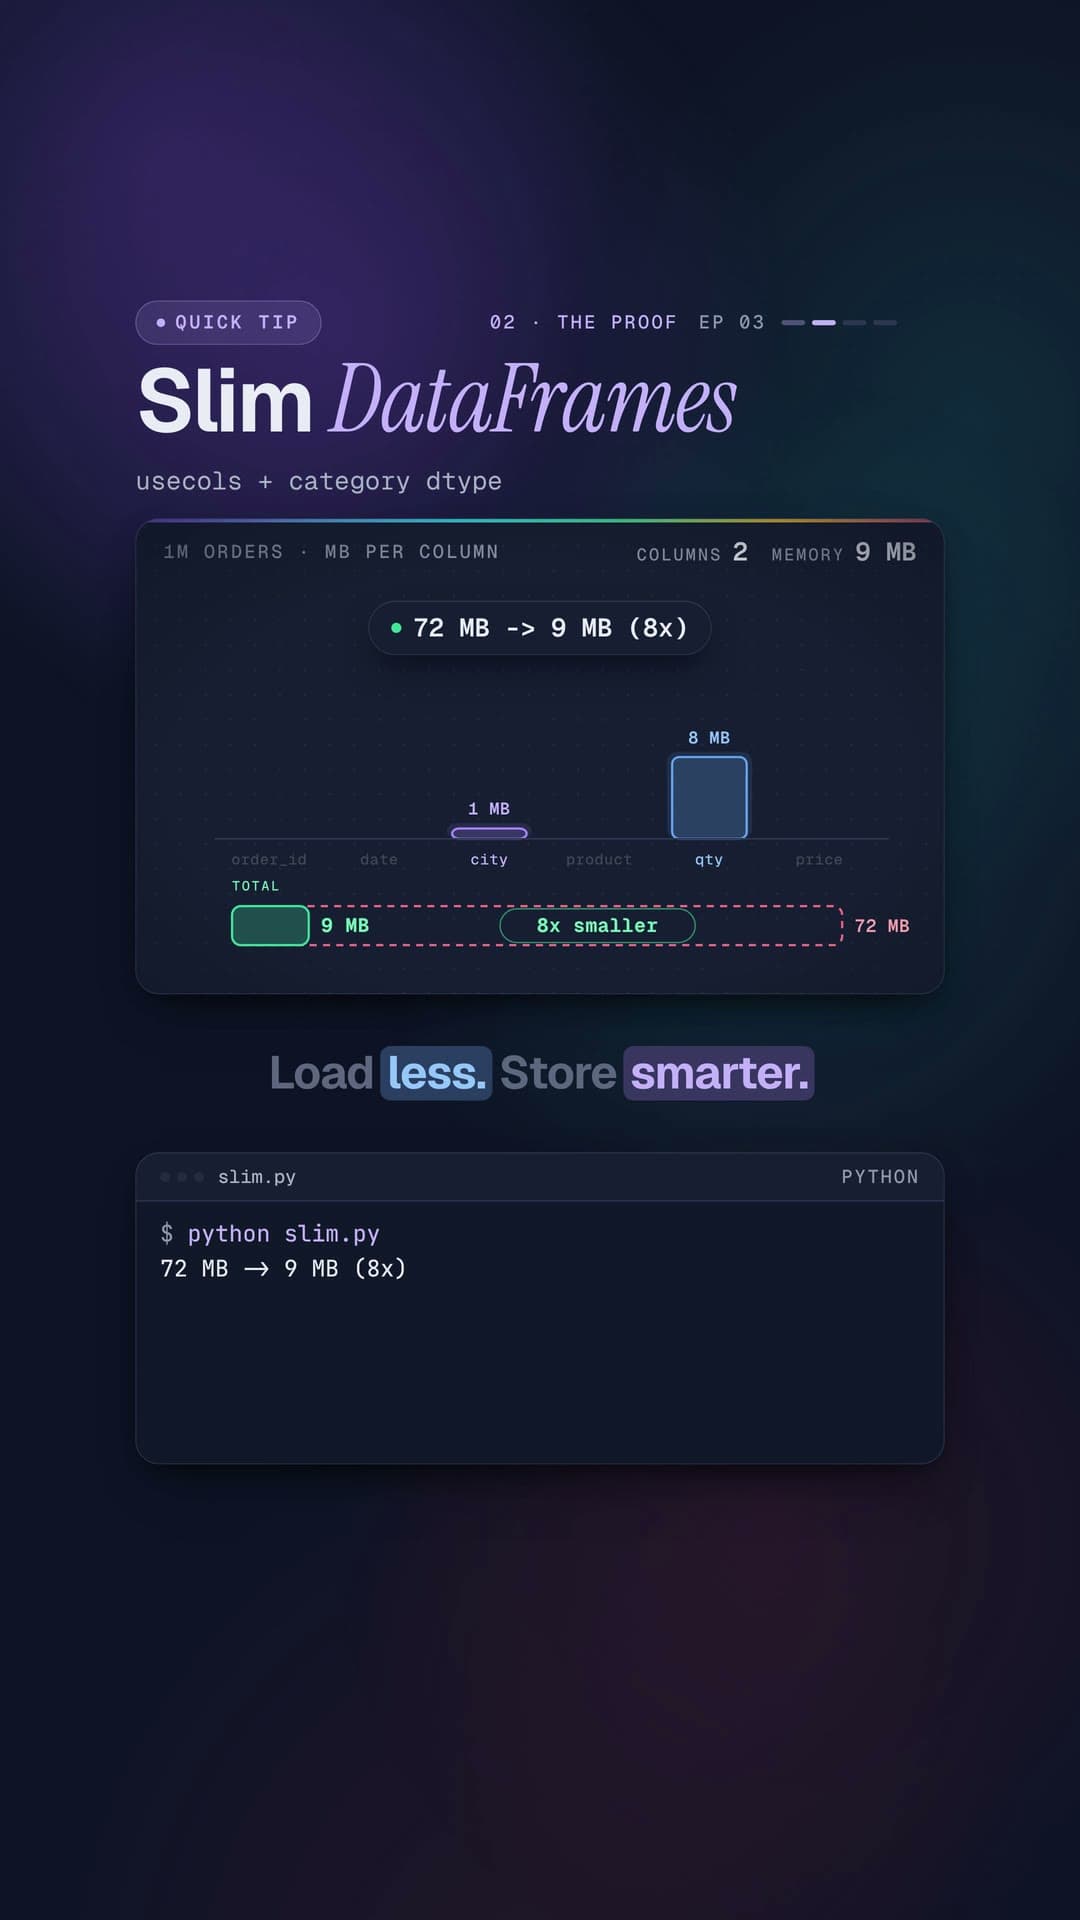
      • Frame from Cut pandas memory 8x: Slim DataFrames, usecols + category dtype0:21Quick tipCut pandas memory 8x
      • Frame from SQL on a CSV, no database: SQL on a CSV file, duckdb: no server, no load step0:22Quick tipSQL on a CSV, no database
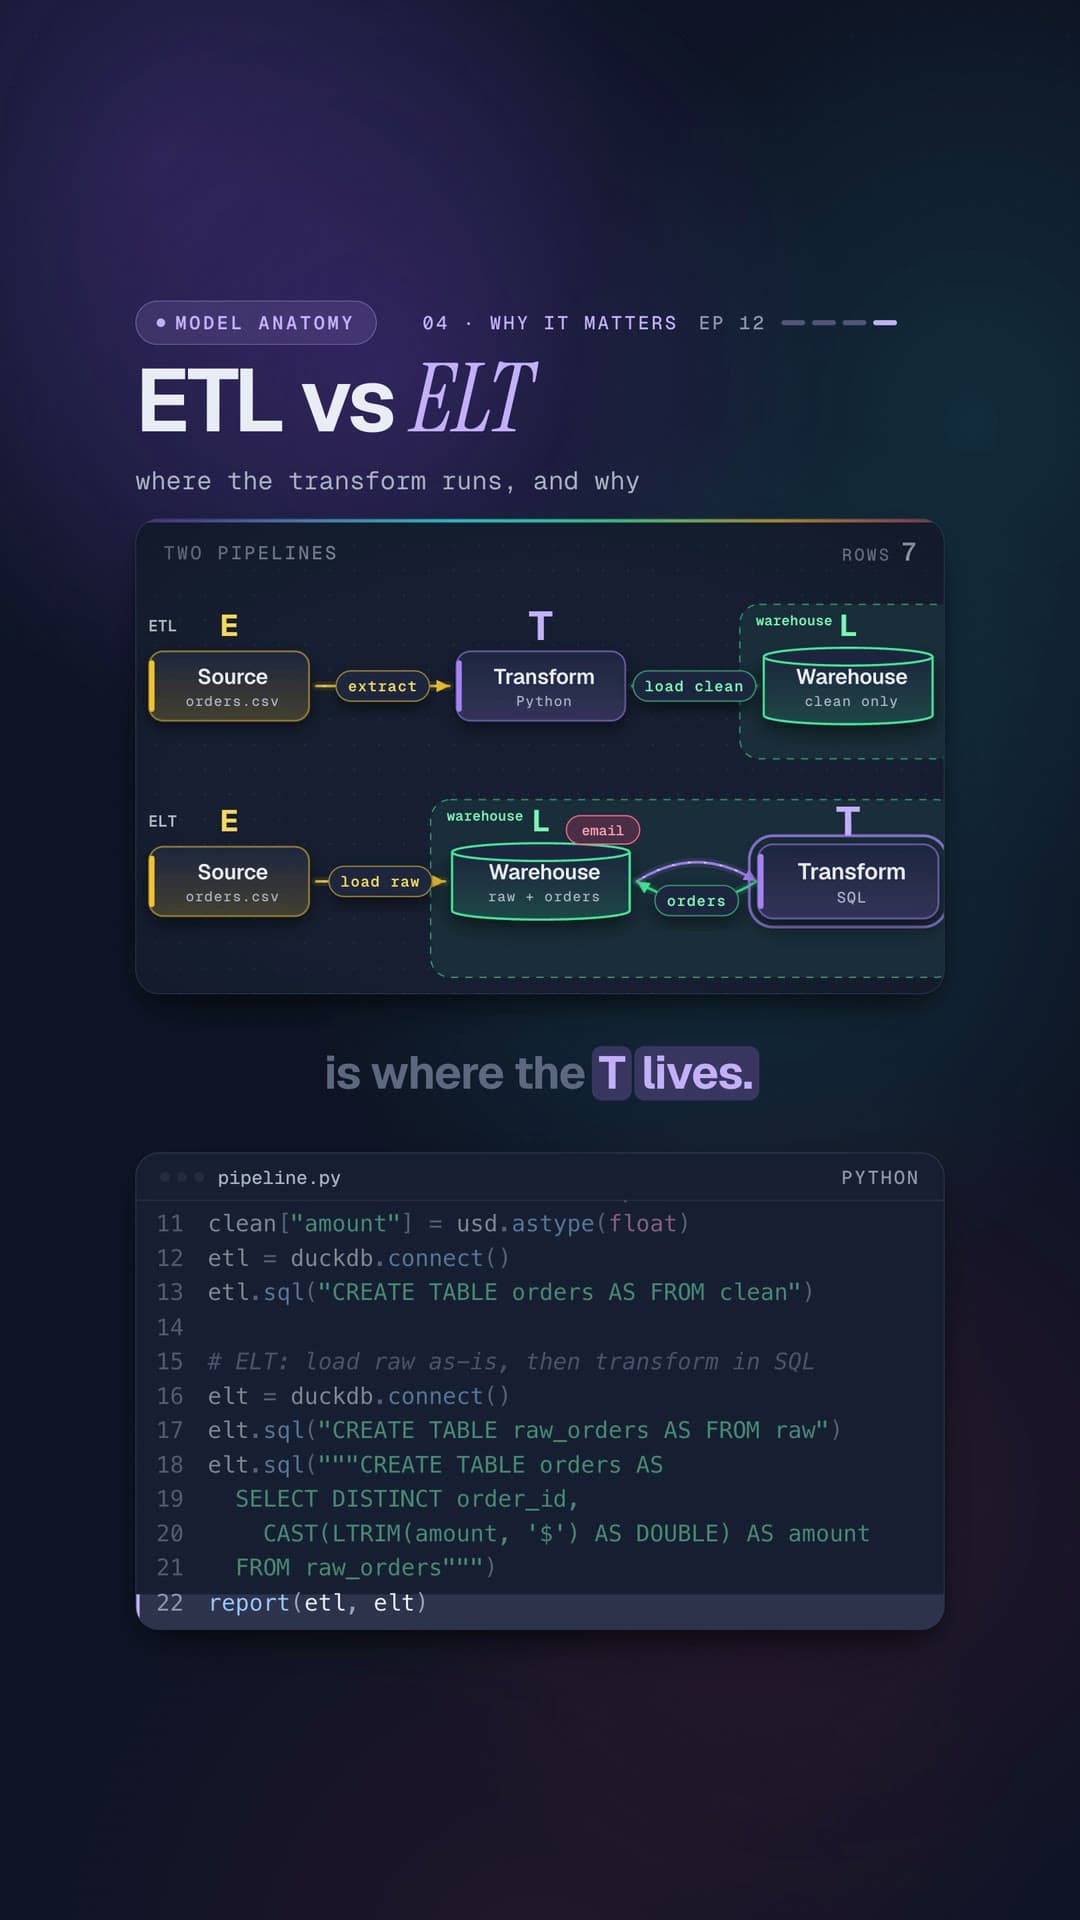
      • Frame from ETL vs ELT: ETL vs ELT, where the transform runs, and why2:21Data engineeringETL vs ELT
      • Frame from Scanned invoices to SQL: Scans to SQL, OCR, JSON, Parquet, DuckDB2:33Build LabScanned invoices to SQL
      • Frame from Search documents by meaning: Scans to RAG, embeddings, LanceDB, retrieval2:25Build LabSearch documents by meaning
      • Frame from API to Parquet in 3 files: API to Parquet, a real data pipeline in 3 files1:44Build LabAPI to Parquet in 3 files
      • Frame from Polars skips work: Why Polars is fast, it reads only what the query needs0:41Data engineeringPolars skips work
      • Frame from Data too big for one machine: How Spark scales, partitions, lazy plan, shuffle0:39Data engineeringData too big for one machine
      • Frame from ETL vs ELT in 30 seconds: ETL vs ELT, transform first, or load first0:39Data engineeringETL vs ELT in 30 seconds
      DatanatomyCode is MIT on GitHub
      YouTubeTikTokInstagramThreadsGitHubRSS